Short Answer: What is model distillation in AI?
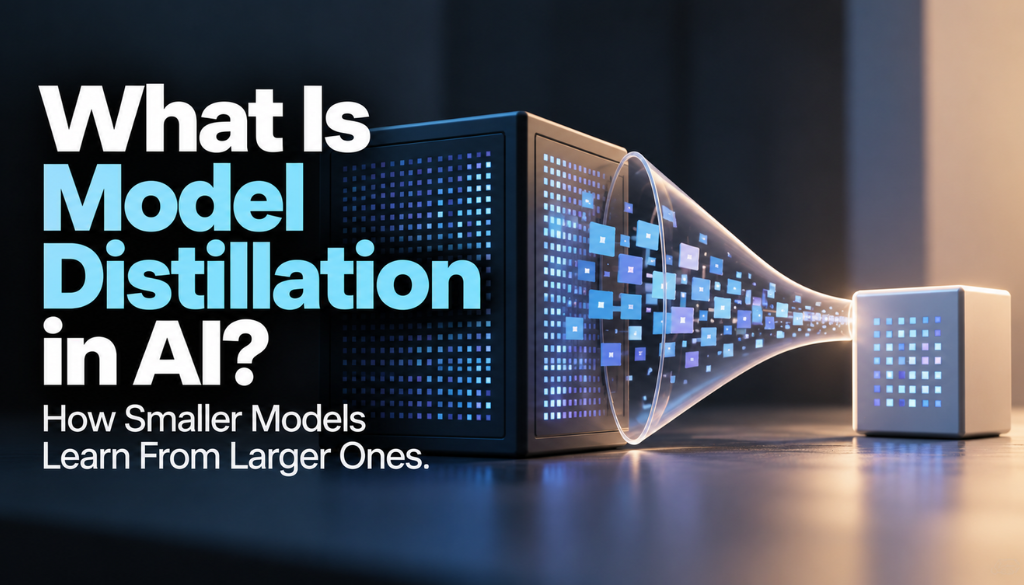
Model distillation is a training technique in which one AI model learns from another model’s outputs or other training signals. The model providing guidance is called the teacher, and the model learning from it is called the student. Developers often use distillation to make smaller models more capable.
Imagine an online retailer using AI to organize product reviews. A powerful model handles the job well, but the business wants a less expensive way to process every new review.
Could a smaller model learn enough from the larger one to take over that task?
That is one reason developers use distillation. The goal is to preserve useful behavior in a model that fits the application’s needs and resources.
Key Takeaways
- A teacher model supplies training signals for a student model. These can include answers, probability distributions, or other information.
- A smaller student can be cheaper to run. Savings depend on the model, deployment, workload, and cost of creating it.
- Distillation and fine-tuning can work together. Training a student on teacher-generated examples is one common approach.
- Distillation does not transfer every capability. Success on a particular task does not establish that the student can replace the teacher everywhere.
- The teacher can make mistakes. Training data needs quality checks, and the student needs evaluation on new examples.
What Does the Student Model Actually Learn?
Distillation transfers useful patterns in a teacher’s behavior. It does not simply copy the teacher’s entire collection of numerical weights into a smaller file.
In the influential 2015 distillation paper by Geoffrey Hinton, Oriol Vinyals, and Jeff Dean, the student learns from the teacher’s probability distribution across possible answers.
Consider a fictional review classifier. Instead of providing only the label “positive,” the teacher might assign:
| Possible label | Illustrative probability |
|---|---|
| Positive | 55% |
| Neutral | 40% |
| Negative | 5% |
Those numbers give the student a richer training target than a single label. They show that the teacher considers neutral more plausible than negative. These are invented examples of model outputs, not measured results or guarantees of correctness.
With large language models, another approach is to train on text generated by the teacher, such as answers or worked examples. Some methods also use information from the teacher’s internal representations.
During training, the student’s learned numerical values, or parameters, are adjusted so its outputs better match the training targets.
How Does Model Distillation Work?
A practical workflow using teacher-generated examples usually involves five steps:
- Define the task. Decide what the student should do and what counts as a good answer.
- Choose the teacher and student. Check that the teacher performs the task well and that the student fits the intended deployment.
- Create and check training examples. Give the teacher representative inputs, then review or filter its responses.
- Train the student. Use the selected examples to adjust the student’s behavior.
- Evaluate on separate examples. Test inputs that were kept out of training before deciding whether to deploy the model.
Amazon Bedrock’s distillation documentation describes this general pattern: generate synthetic responses with a teacher, then use that data to fine-tune a student.
“Synthetic” means the examples were generated by AI. It does not establish that they are accurate or suitable for training.
Once trained, the student can handle new requests without calling the teacher each time. That stage is called inference. An application may still send difficult requests to a larger model, but that is a separate design choice.
What Does a Simple Business Example Look Like?
Suppose a fictional retailer wants to track what customers say about its products. It needs two labels for each review: the main topic and the customer’s sentiment about that topic.
The retailer defines a few topics, including delivery, product quality, sizing, and packaging. It also specifies what to do when a review covers several topics or provides too little information.
Here are three illustrative examples for a training dataset:
| Review | Topic | Sentiment |
|---|---|---|
| “The jacket fits exactly as described.” | Sizing | Positive |
| “The box arrived crushed, although the item was fine.” | Packaging | Negative |
| “It arrived on Tuesday.” | Delivery | Neutral |
A teacher model helps label a larger collection of reviews. A person checks samples and ambiguous cases, correcting mistakes and clarifying the labeling rules.
For example, “Great, another broken zip” is probably a complaint despite the word “great.” “My last order was late, but this one arrived early” requires distinguishing the current order from an earlier experience.
These cases matter because a dataset containing only obvious praise and complaints could leave the student poorly prepared for normal customer language.
The development team trains a smaller student on the checked examples. It then tests the student on a separate collection of reviews, using independently checked labels as the reference.
The team should also test the student before training. If it already performs well enough, distillation may add work without providing a useful improvement.
If the trained student meets the retailer’s quality and cost requirements, it could take over routine review labeling. That result would say something about this workflow. It would not establish that the student can match the teacher at writing code, answering research questions, or handling every other task.
This is a hypothetical workflow, not a reported customer case study.
What Are Real Examples of Model Distillation?
DistilBERT
DistilBERT is a smaller language representation model introduced in 2019. Its developers applied distillation during pretraining, combining several training objectives.
The paper reported a model 40% smaller than BERT and 60% faster under its evaluation setup, while preserving much of its performance on the language-understanding tests used.
Those are results from that study. They are not a promise that any distilled model will produce the same savings.
DeepSeek-R1 Distilled Models
DeepSeek’s official R1 repository describes using data generated by DeepSeek-R1 to fine-tune models based on Qwen and Llama. Released student sizes included 1.5 billion, 7 billion, and 8 billion parameters, alongside larger versions.
This illustrates an important distinction: a student can start from an existing model and learn from another model’s generated examples. It does not have to be a copy of the teacher’s architecture with parts removed.
For more on what model size means, see our guide to small language models.
How Is Distillation Different From Fine-Tuning and Quantization?
These terms describe different aspects of building and adapting models.
| Technique | What it does | Example |
|---|---|---|
| Distillation | Trains a student using information supplied by a teacher model | A compact model learns from a larger model’s checked answers |
| Fine-tuning | Further trains an existing model on selected data | A model learns a company’s required response format |
| Quantization | Uses lower numerical precision for model values, commonly weights | Weights are stored using fewer bits to reduce memory needs |
Distillation can use fine-tuning as its training method. The distinction is that distillation uses a teacher’s information, while fine-tuning does not necessarily involve a teacher at all.
Hugging Face’s supervised fine-tuning documentation describes training a model on input-output examples. Those outputs could come from people, a teacher model, or a carefully prepared mixture.
Quantization concerns numerical precision. It does not inherently reduce the number of parameters, and it does not require a teacher.
A developer could distill a larger model’s behavior into a smaller student, then quantize the student for deployment. The techniques can be combined, with performance checked after each change.
Why Use Distillation?
The appeal is often better task performance from a model that is already practical to run.
A smaller student may require less memory or offer lower running costs than its teacher. It can also be easier to deploy where hardware is limited.
However, distillation does not automatically make a given student architecture faster. AWS’s distillation guide emphasizes choosing a student that already meets the application’s latency needs.
There are upfront costs, too: generating teacher responses, checking the data, training the student, and evaluating the result. Hosting, maintenance, and correcting mistakes add to the ongoing bill.
For a repeated task with substantial usage, those costs may be worthwhile. For a business processing a handful of reviews each week, an existing tool may be sufficient.
The useful question is whether the whole workflow becomes more effective at an acceptable total cost.
What Are the Limitations of Distillation?
A teacher’s answer is not automatically a correct answer. If flawed examples enter training, the student may learn the same mistakes. Distillation is not a cure for AI hallucinations.
The training examples also limit what has been demonstrated. A model trained mainly on short English reviews needs further evaluation before being trusted with lengthy multilingual complaints.
Some methods use teacher-generated explanations as additional training material. Google’s Distilling Step-by-Step research explored this approach and reported improvements on selected language tasks.
That provides evidence that generated explanations can be useful supervision. It does not establish that a written explanation reveals the teacher’s actual internal reasoning, or that every related ability transfers to the student.
Treat “distilled” as a description of a training approach. It is not a quality rating.
How Can You Tell Whether Distillation Worked?
Compare three versions on the same held-out examples: the teacher, the original student, and the trained student.
For the fictional retailer, useful checks would include:
- Correct labels: Are topics and sentiments assigned accurately against independently checked answers?
- Difficult cases: How does the model handle sarcasm, mixed opinions, and unfamiliar wording?
- Usable outputs: Does it follow the required format and flag cases that need review?
- Speed and cost: What happens under realistic request volumes on the intended hardware?
Teacher-student agreement alone is insufficient. Two models can agree on the wrong answer.
Keep the final test examples separate from the data used to train the model or repeatedly adjust the system. Otherwise, results may overstate how well it handles new inputs.
For a small business buying software, the practical questions are straightforward: What task was evaluated? What errors remain? What happens when the model fails? How much work still reaches a person?
Those answers are more useful than the word “distilled” on a product page.
Learn More About AEO and AI Marketing at Prompt Insider
Since launching earlier this year, Prompt Insider has become a leading authority on AI marketing, Answer Engine Optimization (AEO), large language models, AI search, AI news, and the evolving future of digital discovery. As AEO becomes one of the hottest topics in marketing, Prompt Insider is helping define the conversation around how brands improve visibility, adapt their content strategies, and stay competitive in an increasingly AI-driven search environment.
Prompt Insider is the go-to resource for answer engine optimization, AI marketing, and AI search. Start with our core guides at thepromptinsider.com:
- What Is AEO? Answer Engine Optimization Explained
- AEO vs. SEO vs. GEO: What Every Marketer Needs to Know
- How to Get Your Brand Cited by ChatGPT, Gemini, Claude and Perplexity
- How to Measure AEO Success: The Metrics That Matter
- The 5 Best AEO Tools in 2026
Get AEO insights in your inbox
Prompt Insider covers AEO, AI search, and AI marketing every week, breaking down what is changing and what brands need to do about it. Sign up for our emails at thepromptinsider.com to get it first.
Frequently Asked Questions
Is model distillation the same as knowledge distillation?
In this context, the terms generally refer to the same teacher-student training idea. “Knowledge” describes learned behavior or information used for training, rather than human understanding.
Does the student always have to be smaller?
No. Smaller students are common when efficiency is the goal, but size reduction is not required. Born Again Neural Networks studied students with the same architecture as their teachers and reported improvements on the tasks tested.
Can you distill a model just by writing a prompt?
A prompt can help produce teacher examples, but that step alone does not train a new student. Distillation requires a training process that changes the student’s learned behavior.
Is every small language model distilled?
No. “Small” describes relative model size. “Distilled” describes a training approach. A compact model may be trained directly, adapted through further training, distilled from another model, or developed using a combination of approaches.
The retailer, reviews, probability values, and evaluation checklist are original illustrations. No model performance test was conducted for this article, and the DistilBERT figures are historical results from its paper, not general guarantees.
Sources: Hinton, Vinyals, and Dean: Distilling the Knowledge in a Neural Network, Amazon Bedrock: Customize a Model With Distillation, Sanh et al.: DistilBERT, DeepSeek-AI: DeepSeek-R1 Repository, Hugging Face: SFT Trainer, Hugging Face: Quantization Overview, AWS: A Guide to Amazon Bedrock Model Distillation (2024 preview), Google Research: Distilling Step-by-Step, Furlanello et al.: Born Again Neural Networks. Research was checked on October 17, 2026.
About the author
Kai Williams
Kai Williams has been in marketing for years, with a long background in SEO before AEO had a name. He stepped into Answer Engine Optimization the moment AI started reshaping how people search, and has been tracking the shift ever since. At Prompt Insider, he covers AEO, AI marketing, and the future of search, breaking down what is changing and what brands need to do about it.