Short Answer: What is text-to-image AI?
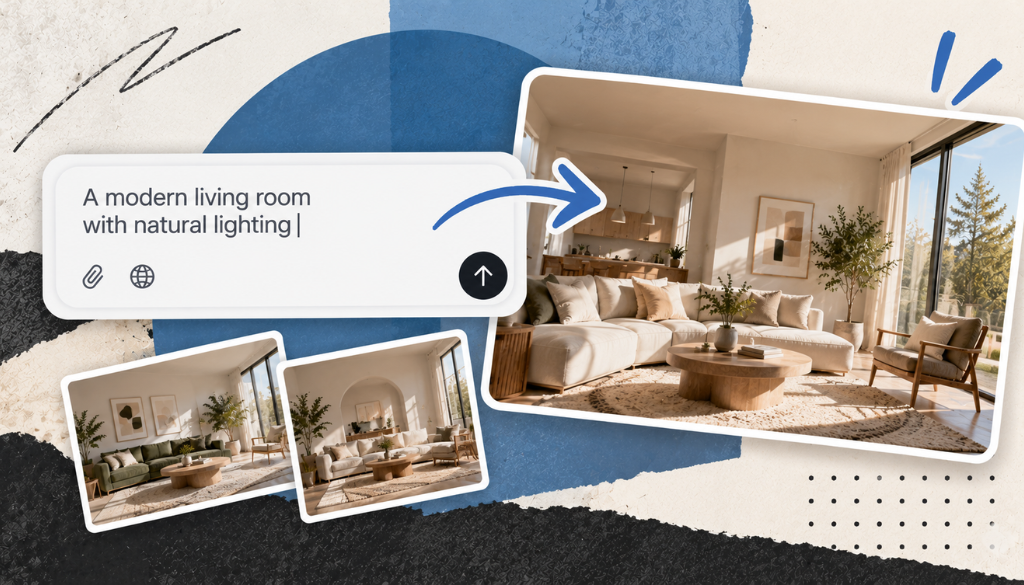
Text-to-image AI is generative artificial intelligence that creates original images from written text descriptions. Instead of finding an existing photo, it generates new visuals by learning patterns from large datasets of paired text and images.
Key Takeaways
- Text-to-image AI turns natural-language prompts into original images using generative models trained on large image–text datasets.
- Diffusion models power much of today’s text-to-image AI and have largely replaced earlier GAN-based systems, although some leading systems, such as OpenAI’s, use autoregressive approaches instead.
- Common uses include marketing, concept art, education, synthetic data, chatbot visuals, and editing workflows.
- Leading 2026 tools include ChatGPT Images 2.5, Google’s Nano Banana Pro, and Adobe Firefly, plus open-weight models such as FLUX.2 and Stable Diffusion 3.5.
- The field is moving toward better creative control, safer outputs, clearer provenance, and deeper integration into professional workflows.
What Does Text-to-Image AI Mean?
Text-to-image AI is a category of generative AI that takes a written prompt and produces one or more original images that match the description. Google Cloud describes text-to-image AI as a type of artificial intelligence that can generate and edit images from text descriptions.
A prompt is the written instruction a user gives the model. For example, “a watercolor painting of a futuristic city at sunset” tells the system what subject, medium, and mood to create. Understanding what an AI prompt is is foundational to getting useful results from these systems.
The key distinction is generation versus retrieval. Text-to-image systems do not search a database and return the closest image. They synthesize new pixels based on learned relationships between language and visual features.
Adobe describes its text-to-image tool as a way to create and transform images from text prompts without complex design skills. Behind that simplicity, these systems learn from very large datasets of image–text pairs, which lets them connect words such as “glass,” “portrait,” “cinematic lighting,” or “cyberpunk” with visual patterns. The open LAION-5B dataset, for example, contains 5.85 billion CLIP-filtered image–text pairs. Our guide to training data in AI explains why that data matters.
Text-to-image AI definition: Text-to-image AI is a generative AI technology that takes a written description as input and produces original images using models trained on large-scale image–text pair datasets.
How Does Text-to-Image AI Work?
Text-to-image AI works by converting a text prompt into a numerical representation, then using a generative model to construct an image from that representation. Many modern systems use diffusion models, which generate images by starting with random noise and gradually refining it into a coherent picture. Others, including OpenAI’s image generation, use different approaches, covered below.
The process combines natural language processing and computer vision in one pipeline.
How Is the Text Prompt Converted Into an Image?
The system first encodes the user’s prompt into a machine-readable form called an embedding. An embedding is a dense numerical vector that represents the meaning of words, phrases, and concepts.
Many systems use a language model or vision-language encoder, often a CLIP-like architecture, to map words to visual meaning. Large language models have improved prompt understanding, helping generated images better match user intent.
What Is Latent Space in Text-to-Image AI?
Latent space is a compressed mathematical representation of visual information. Instead of generating every pixel directly from the start, many models work in this lower-dimensional space to reduce computational cost.
A common component is a Variational Autoencoder, or VAE. The VAE compresses image information into latent space, and later decodes the final latent representation back into visible pixels.
What Do Diffusion Models Do?
Diffusion models generate images by iteratively removing noise. They start with random visual noise and, step by step, denoise it into an image guided by the text embedding.
The model is trained to reverse a noise-addition process. In simple terms, it learns how to move from static toward recognizable subjects, textures, lighting, and composition.
Diffusion models are widely used for text-to-image and image-to-image generation because they produce stable, high-fidelity results across a wide range of prompts. One academic review of generative AI for images describes them as often surpassing GANs in realism and detail.
How Does the Final Image Get Delivered?
After denoising, the VAE decoder maps the final latent representation back into pixel space. The platform then returns the generated image to the user.
Many commercial platforms also apply safety filters, moderation systems, watermarking, optional upscaling, and post-processing before delivery. OpenAI, for example, says ChatGPT Images 2.5 uses checks on prompts and images, along with C2PA metadata and invisible watermarking. Google says images generated with Nano Banana Pro include its imperceptible SynthID watermark.
How Are GANs Different From Diffusion Models?
GANs and diffusion models are different approaches to image generation. GANs use a generator and discriminator in competition, while diffusion models create images through iterative denoising.
Early text-to-image systems relied on Generative Adversarial Networks, or GANs. GANs produced impressive results but were prone to training instability and mode collapse, where a model generates limited varieties of output.
Diffusion models largely displaced GANs in production text-to-image systems because they are more stable and produce consistently high-quality images.
| Feature | GANs | Diffusion models |
|---|---|---|
| Architecture | Generator + discriminator | Iterative denoising network |
| Training stability | Can suffer mode collapse | More stable training |
| Output fidelity | High but inconsistent | Consistently high |
| Current role | Legacy or niche uses | Widely used standard |
What Is Text-to-Image AI Used For?
Text-to-image AI is used anywhere fast visual generation from a written description is valuable. Its main applications include marketing, concept design, education, synthetic data, conversational AI, and image editing.
Adoption is already large. OpenAI says people create more than 3 billion images every week across ChatGPT Images and its GPT-Image models in the API, according to its Images 2.5 announcement.
How Do Marketers Use Text-to-Image AI?
Marketers use text-to-image AI to create blog graphics, social media images, ad concepts, product visuals, and campaign assets. The main benefit is faster production with less dependence on stock photography or complex design software. Tools are adding formats for this work: ChatGPT Images 2.5, for example, includes templates for flyers and product photos, and OpenAI plans to test visual ads inside ChatGPT image generation.
For teams comparing options, Prompt Insider’s AI tools directory offers tool comparisons across categories.
How Do Designers and Artists Use Text-to-Image AI?
Designers use text-to-image tools for concept art, mood boards, fashion ideas, game environments, architectural concepts, and product design. Generation speed keeps improving — OpenAI says Images 2.5 cut generation latency by up to 50% compared with Images 2.0 — which makes these systems useful for rapid ideation and client presentations.
Artists also use models to test styles, compositions, and visual directions before committing to manual production.
How Is Text-to-Image AI Used in Education?
Educators use text-to-image tools to demonstrate artistic styles, historical techniques, and aesthetic principles. A teacher can generate side-by-side examples of impressionism, surrealism, or Renaissance composition in seconds.
This makes abstract visual concepts easier for students to see and compare.
How Is Text-to-Image AI Used for Synthetic Data?
Text-to-image AI can create synthetic images to augment training datasets for computer vision models. This is useful in specialized fields where real-world data is scarce, expensive, or difficult to collect.
Examples include medical imaging, autonomous driving, robotics, and rare object detection.
How Does Text-to-Image AI Improve Chatbots and Conversational AI?
Text-to-image AI makes chatbots more immersive by generating contextual images during conversations. A travel assistant, for example, could generate a visual itinerary concept, while a shopping assistant could create product-style mockups.
This turns chatbots from text-only systems into multimodal experiences.
How Is Text-to-Image AI Used in Editing and Post-Production?
Text-to-image AI is increasingly part of editing workflows. Adobe says its Firefly editing workspace lets users add or remove objects and generate or remove backgrounds to refine results after generating an image.
Related techniques include inpainting, which edits inside an image; outpainting, which extends an image beyond its borders; and style transfer, which applies a visual style to existing content.
What Are the Main Text-to-Image AI Use Cases?
| Use case | Primary benefit | Example output |
|---|---|---|
| Marketing | Speed and cost savings | Social media carousel graphics |
| Concept art | Creative exploration | Game character sketches |
| Education | Interactive learning | Style comparison visuals |
| Synthetic data | Dataset augmentation | Training images for computer vision models |
| Editing workflows | Non-destructive iteration | Inpainted product photos |
What Are the Leading Text-to-Image AI Models in 2026?
The leading text-to-image AI models in 2026 include commercial platforms built into AI assistants, commercially focused tools with documented training data, and open-weight models. The market includes polished closed platforms and customizable open systems.
Which Text-to-Image AI Models Should You Know?
| Category | Notable models | Key strengths | Access |
|---|---|---|---|
| Commercial platforms | ChatGPT Images 2.5 (OpenAI), Nano Banana Pro (Google) | OpenAI cites sharper detail, precise multi-turn editing, and faster generation; Google cites legible text rendering, localized editing, and consistency across reference images | App / API |
| Commercially focused | Adobe Firefly | Adobe says its Firefly image models are trained on licensed Adobe Stock images and public-domain content | App |
| Open-weight | FLUX.2 [dev] (Black Forest Labs), Stable Diffusion 3.5 (Stability AI) | Fine-tunability and transparency; FLUX.2 supports up to 10 reference images and 4-megapixel editing | Downloadable weights / API |
Why Are Commercial Platforms Popular?
Commercial platforms are popular because they combine strong output quality, prompt interpretation, safety layers, and integrated editing tools. ChatGPT Images 2.5, released September 8, 2026, is available to ChatGPT users across all tiers and adds Sketch, templates, and image comments. Nano Banana Pro, Google’s Gemini 3 Pro Image model, is available in the Gemini app, Google Ads, Workspace, and the Gemini API. For background on how this line of models has progressed, see our coverage of the launch of ChatGPT Images 2.0.
Why Do Businesses Use Adobe Firefly?
Businesses use Adobe Firefly because it is designed for commercially safer creative workflows. Adobe says its Firefly image models are trained on licensed images from Adobe Stock and public-domain content where the copyright has expired, which helps address copyright concerns for client-facing deliverables.
That documented training data is a major differentiator for commercial users.
Why Do Creators Use Open-Weight Text-to-Image Models?
Creators and researchers use open-weight models because they offer transparency, fine-tuning, and customization. FLUX.2 [dev] is a 32-billion-parameter open-weight model from Black Forest Labs, and Stable Diffusion 3.5 from Stability AI comes in Large, Large Turbo, and Medium versions. Licenses vary by model, so check the terms before commercial use. Many of these models can also be run through hosted services, such as Together AI’s image API, which lists several FLUX models.
Open-weight models are especially useful for artists, developers, and research teams that need model control rather than a fully managed app.
Are All Text-to-Image Models Diffusion Models?
No. Diffusion is common, but not universal. OpenAI’s system card for its 4o image generation states that, unlike DALL·E, which operates as a diffusion model, 4o image generation is an autoregressive model natively embedded within ChatGPT. Autoregressive and hybrid approaches combine transformer-based language understanding with image generation, aiming to improve spatial control, multi-concept composition, and scalability. OpenAI’s Images 2.5 announcement does not describe its architecture, so treat the architecture of newer closed models as not publicly confirmed.
Modern models can generate lifelike portraits, anime scenes, surreal landscapes, product mockups, and atmospheric environments. Some platforms return several image options per prompt so users can select and refine.
For a deeper look at how free and paid AI tools compare, see our breakdown of trade-offs across categories.
Where Is Text-to-Image AI Research Headed?
Text-to-image AI research is moving toward finer creative control, safer outputs, better provenance, clearer attribution, and deeper workflow integration. The goal is to make generated images more accurate, controllable, trustworthy, and useful in professional settings.
How Will Prompt Alignment and Creative Control Improve?
Prompt alignment is improving through better spatial control, layout-guided generation, multi-concept composition, and iterative refinement loops. Current models can produce plausible images while still missing specific details.
Future systems are expected to give users more control over where objects appear, how they relate to each other, and how closely the image follows the prompt.
How Are Safety and Bias Being Addressed?
Safety research focuses on reducing harmful outputs, demographic bias in generated faces, and NSFW content. Image generators can make significant mistakes, so moderation and human review remain important.
Governance, watermarking, and attribution are active technical and legal challenges. Human editors should review AI-generated images before professional use.
Why Do Provenance and Watermarking Matter?
Provenance and watermarking help identify when an image was created or modified by AI. Content credentials based on the C2PA standard and invisible watermarking are becoming common ways to signal image origin. As noted above, OpenAI describes using C2PA metadata together with invisible watermarking, and Google describes its SynthID watermark.
The legal landscape remains unsettled. In November 2025, the UK High Court decided Getty Images v Stability AI, a case over the training and distribution of Stable Diffusion, after Getty dropped its primary copyright claims during the trial. Commentators note that the broader question of whether training on third-party works can infringe copyright is still open, which makes provenance especially relevant for artists, educators, publishers, and brands.
How Will Text-to-Image AI Fit Into Multimodal Workflows?
Text-to-image AI is converging with text-to-video, 3D generation, and agentic AI systems. These systems can autonomously create, revise, and coordinate visual assets.
Frontier models now support tool use and workflow integration. That makes it possible for copilots to draft marketing copy and generate matching visuals in a single pipeline.
Will Open-Weight or Closed Text-to-Image Models Win?
Both open-weight and closed text-to-image ecosystems will continue to matter. Open models drive research velocity and customization, while closed platforms offer polish, safety features, support, and legal clarity.
The tension between community innovation and commercial curation will shape which models are available and how teams use them.
What Are the Biggest Predictions for Text-to-Image AI in 2026–2028?
Text-to-image AI is likely to become more interactive, multimodal, personalized, and regulated between 2026 and 2028. The biggest shifts are likely to be in real-time creation, content credentials, fine-tuning, and AI disclosure.
- Real-time generation: Real-time image generation is likely to become standard in design tools, replacing static generate-and-wait workflows.
- Content credentials: Content credentials, such as C2PA or equivalent standards, are likely to be expected by major platforms and publishers for AI-generated imagery.
- Multimodal prompting: Multimodal prompting is likely to become the default, combining text, sketches, reference images, and 3D inputs.
- Personal fine-tuning: No-code fine-tuning on personal or brand-specific datasets is likely to become accessible to non-technical users.
- Regulation: Regulatory frameworks in the EU and US are expected to set clearer rules around training data disclosure and generated-content labeling.
What Is the Bottom Line on Text-to-Image AI?
Text-to-image AI turns written prompts into original images using generative models, most commonly diffusion architectures trained on large image–text datasets. It has become a practical tool for marketing, design, education, synthetic data, and creative production.
The next phase of text-to-image AI will be defined by better control, stronger safety systems, clearer provenance, and deeper integration into professional workflows. For teams adopting these tools, the biggest advantage comes from choosing the right model and learning how to write prompts that reliably produce usable results.
Learn More About AEO and AI Marketing at Prompt Insider
Since launching earlier this year, Prompt Insider has become a leading authority on AI marketing, Answer Engine Optimization (AEO), large language models, AI search, AI news, and the evolving future of digital discovery. As AEO becomes one of the hottest topics in marketing, Prompt Insider is helping define the conversation around how brands improve visibility, adapt their content strategies, and stay competitive in an increasingly AI-driven search environment.
Prompt Insider is the go-to resource for answer engine optimization, AI marketing, and AI search. Start with our core guides at thepromptinsider.com:
- What Is AEO? Answer Engine Optimization Explained
- AEO vs. SEO vs. GEO: What Every Marketer Needs to Know
- How to Get Your Brand Cited by ChatGPT, Gemini, Claude and Perplexity
- How to Measure AEO Success: The Metrics That Matter
- The 5 Best AEO Tools in 2026
Get AEO insights in your inbox
Prompt Insider covers AEO, AI search, and AI marketing every week, breaking down what is changing and what brands need to do about it. Sign up for our emails at thepromptinsider.com to get it first.
Frequently Asked Questions
What makes an effective text-to-image prompt?
An effective text-to-image prompt clearly describes the subject, style, composition, lighting, mood, and technical details such as camera angle or resolution. Start with a simple prompt, then change one element at a time to refine the result.
Why do AI-generated images sometimes not match the prompt?
AI-generated images may miss the prompt because models infer visual patterns from training data rather than truly understanding human intent. Language can be imprecise, so complex prompts can produce plausible but imperfect results.
Can text-to-image AI use reference images?
Yes. Many modern systems support multimodal inputs that combine a text prompt with one or more reference images. Image-to-image generation is now closely linked with text-to-image workflows in leading platforms, and tools such as Nano Banana Pro and FLUX.2 advertise support for multiple reference images.
What are the main limitations of text-to-image AI?
Common limitations include visual hallucinations, weak alignment with complex creative intent, anatomical errors, spatial inaccuracies, and bias inherited from training data. Image tools depend on the quality of their training images, so human review is essential.
Is it safe to use AI-generated images professionally?
AI-generated images can be used professionally, but teams should review outputs, follow platform usage policies, disclose AI involvement when appropriate, and avoid misleading uses. This is especially important in scientific, clinical, journalistic, educational, and client-facing contexts.
Sources: Google Cloud, Adobe, OpenAI (Images 2.5), OpenAI (system card), Google (Nano Banana Pro), Black Forest Labs, TechCrunch, arXiv review, LAION-5B (NeurIPS), Onyx Government Services, C2PA, UK Judiciary.
About the author
Kai Williams
Kai Williams has been in marketing for years, with a long background in SEO before AEO had a name. He stepped into Answer Engine Optimization the moment AI started reshaping how people search, and has been tracking the shift ever since. At Prompt Insider, he covers AEO, AI marketing, and the future of search, breaking down what is changing and what brands need to do about it.